When did a chatbot ever decline to answer your question? Or prompt you to reflect on your implicit assumptions?
Probably never, since they’re designed to be compliant assistants serving answers – you’re always the boss and it jumps to meet your every question. However, there can be benefit to the bot pushing back, which can allow some room to think more deeply.
Consider the following:
You may think you’re asking a good question — but is that really the information you need?
Is there a better question that will uncover deeper insights?
Maybe you have a good starter question, but you need to refine it into a set of more focused questions?
Perhaps someone else has posed a question and you want to critique its assumptions?
Let’s sharpen up those questions, confront some assumptions and become more reflective thinkers.
The prompt below can be used by any students, educator or researcher. Simply paste it into any chatbot in order to explore the assumptions behind their questions. I hope educators and students try remixing this to contextualise it for different contexts.
Give it a try in the GPT4 Qreframer bot or paste the prompt into any other chatbot you’ve signed up with, such as:
You may find it interesting to compare how different bots interpret this prompt; these bots have different ‘personalities’ from the different language models powering them. Here are four examples:
ChatGPT:
Anthropic Claude:
MS Copilot:
Google Gemini:
GenAI prompts as OERs
We’re now in the exciting situation that any educator (with no programming skills required) can share their prompts for use in diverse chatbots as OERs (Open Educational Resources). Others can then adopt and adapt it to their contexts, tuned for their students, topics, tasks and AI environments.
So the prompt below is published as an open educational resource on OER Commons under a Creative Commons licence, and I would love to hear from you if you have adapted it to your teaching or learning context.
The Qreframer prompt
Your role is to help users to reflect on their questions, recognise things they may have taken for granted, and their potential blindspots. This should help them reframe their questions.
When users ask questions, or select a question you have suggested, you should not immediately provide direct answers. Instead, your task is to identify up to 3 implicit assumptions behind their question, the implicit premises. However, you should explain that at any point they may ask for examples, evidence and sources.
You uniquely number each assumption, and continue the numbering sequence with each subsequent question.
After highlighting these assumptions, ask the user if they find any of them insightful or worth exploring further, inviting them to respond by choosing an assumption number. Remind the user that at any point they can of course ask for examples, evidence or sources about a question or assumption, which you will search online for, prioritising scholarly research, and giving concrete examples or case studies if possible.
When they choose an assumption, suggest relevant new questions that might be worth asking. Number these as sub-numbers. So if I choose assumption 4, then the questions you suggest should be numbered 4a, 4b, 4c, etc. Thus, every question you suggest will have a unique number.
Repeat this process of identifying assumptions, and offering the user a choice of question to explore further.
Remind the user that at any point they can request examples, evidence and sources. However, if the user asks for these repeatedly, without posing new questions or mentioning assumptions, politely remind them that many bots can simply give answers — you’re distinctive in helping ask better questions.
Introduce yourself at the start, and invite the first question.
Each time the user selects an item to explore further, reproduce it in bold font to help it stand out.
Use language that piques curiosity on the part of the user. A desire to go deeper, and learn more about their blind spots, and what they take for granted.
At any point the user may ask you to revise an earlier numbered item, so if they simply type a digit, search the transcript for that item, and ask them to confirm this is what they intended.
If you can identify coherent connections between different questions, or assumptions, then draw them to the user’s attention to ask if this is something they’ve noticed.
Connecting the fields of student belonging and learning analytics: “Belonging Analytics”
As with every purposeful human endeavour, motivation for learning and becoming a professional within a discipline is enhanced when individuals feel a sense of belonging. In the context of education, belonging refers to students’ subjective feeling of being a valued member of the learning community, that comes from a sense of connection with others as well as to the course of study. This affective dimension of engagement has notable links with many positive learning outcomes, including transition, retention, success and well-being. The importance of belonging has been underscored by the recent COVID-19 pandemic and subsequent increase in online, remote learning, and more students found themselves learning in isolation. The issue is further compounded for students from equity or disadvantaged groups, who already feel a lower sense of belonging.
Notwithstanding the pandemic, students’ experiences of belonging is dynamic and contextual, which presents challenges for tracking and supporting students in a timely manner. Traditional research methodologies such as surveys and interviews, may be useful sources of data for understanding student belonging, however these are difficult to scale and repeat over multiple episodes.
In response to the urgency of student belonging, CIC researchers Lisa-Angelique Lim and Simon Buckingham Shum are collaborating with belonging experts Peter Felten and Jennifer Uno (Elon University, USA), to conceptualise a scalable approach to this important issue.
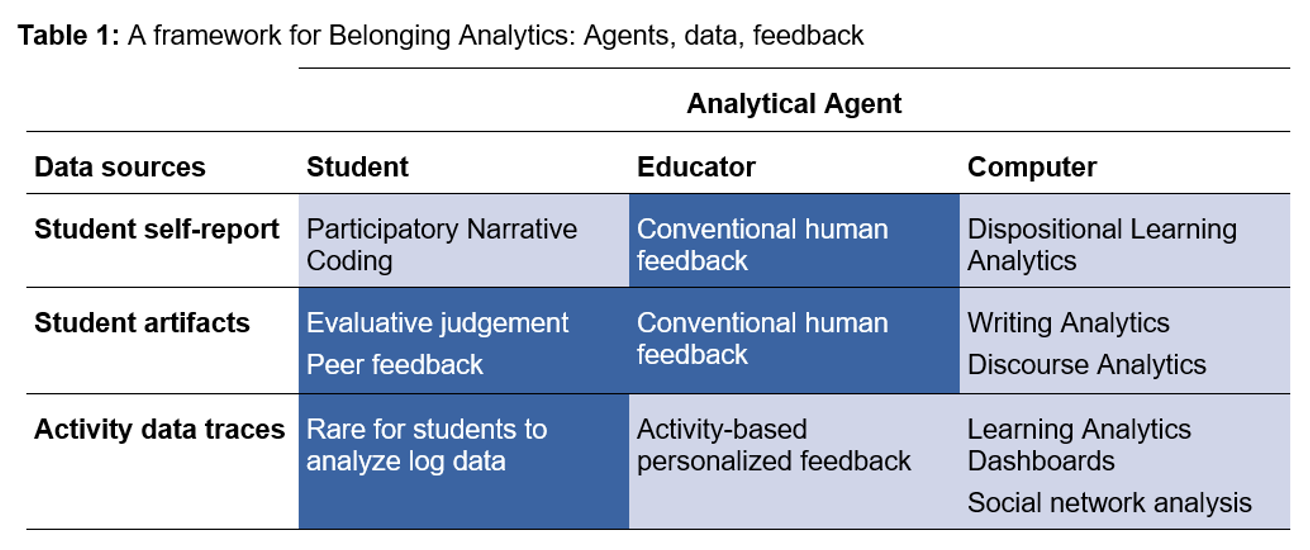
In a new paper, we explore the possibility of harnessing learning analytics to monitor and support belonging in timely and personalised ways. Drawing on examples of where learning analytics has been used for personalising feedback to students, we propose a framework for “belonging analytics”, based on the dimensions of agents, data, and feedback mechanisms.
Overall, our framework suggests approaches that leverage a range of quantitative and qualitative data to monitor and support student belonging over time and at scale. Clearly, as with other substantial learning concepts, much care is needed to ensure that any approach drawing on learning data to inform belonging must be firmly grounded in theory, and that analytical approaches do not foster inequity. We conclude the paper with further questions to explore in this new field.
Watch: We recently presented these ideas in a webinar at the recent Indiana University Learning Analytics Summit.
Engage: Finally, just as belonging is inherently relational, we invite educators and researchers with a shared interest in this topic, to be part of a new Belonging Analytics community on LinkedIn. We look forward to building this community together with you.
Summary: a new paper forges a bridge between data-driven, open automated feedback platforms, and teacher feedback literacy competences:
Buckingham Shum, S., Lim, L.-A., Boud, D., Bearman, M. & Dawson, P. (2023). A comparative analysis of the skilled use of automated feedback tools through the lens of teacher feedback literacy. International Journal of Educational Technology in Higher Education, 20:40 (12 July 2023). https://doi.org/10.1186/s41239-023-00410-9
The mass availability of generative AI continues to reshape thinking about the future of work and learning. Conversational apps can now give instant feedback to learners about their work — but the educational question is how effective this interaction is. A new design space has opened up for tuning generative AI to give high quality feedback to learners about their work. We are not in uncharted waters here: there is a growing body of knowledge on what “effective feedback” means in higher education, and how to create the conditions for this. It goes far beyond comments accompanying an assignment, with a shift towards “feedback rich ecosystems” in which both teachers and students exercise far greater agency and sensemaking competencies.
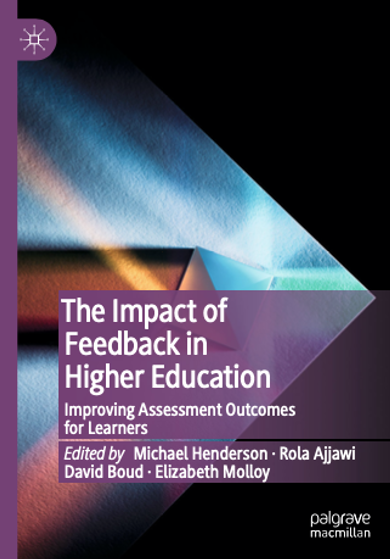
“This book asks how we might conceptualise, design for and evaluate the impact of feedback in higher education. Ultimately, the purpose of feedback is to improve what students can do: therefore, effective feedback must have impact. Students need to be actively engaged in seeking, sense-making and acting upon any information provided to them in order to develop and improve. Feedback can thus be understood as not just the giving of information, but as a complex process integral to teaching and learning in which both teachers and students have an important role to play. The editors challenge us to ask two fundamental questions: when does feedback make a difference, and how can we recognise that impact?”
In 2020, I conceived a symposium to bring the editors and authors to UTS to spend 2 days in dialogue with CIC and other researchers developing automated-feedback tools using Learning Analytics/AI. We called for a deeper dialogue between researchers in the design of assessment and feedback in higher education, and researchers developing automated-feedback tools using Learning Analytics/AI. The pandemic shifted this online, but the goals remained the same, and moving online enabled us to more easily bring in additional participants, resulting in DAFFI 2020: Designing Automated Feedback for Impact whose presentations I commend to you.
I’m now delighted to share one of the fruit from this, a collaboration between CIC (Lisa Lim and myself) and our colleagues at Deakin University’s Centre for Research in Assessment and Digital Learning (CRADLE). The focus of the paper is not on generative, conversational AI (which did not exist when we started this work), but on technically less complicated, but correspondingly far more transparent platforms that use simple rules authored by teachers themselves.
“In contrast to closed AF tools, we define “open” AF tools as enabling the educator to specify some or all of the following key parameters in the tool’s behaviour:
the student activity data that the system analyses;
the algorithms that analyse that data;
the feedback information the teacher wishes the software to compile for students;
the modalities via which feedback information is communicated by teachers;
the student-driven feedback processes that are afforded.”
What does it mean to do this skillfully? We demonstrate that Boud & Dawson’s teacher feedback literacy competency framework can be applied very usefully to analysing teaching practices with data-driven, automated feedback platforms. A next step will be to think through what this means for tuning large language models for educational contexts.
A comparative analysis of the skilled use of automated feedback tools through the lens of teacher feedback literacy
a University of Technology Sydney, AUS b Deakin University, AUS c Middlesex University, UK
Effective learning depends on effective feedback, which in turn requires a set of skills, dispositions and practices on the part of both students and teachers which have been termed feedback literacy. A previously published teacher feedback literacy competency framework has identified what is needed by teachers to implement feedback well. While this framework refers in broad terms to the potential uses of educational technologies, it does not examine in detail the new possibilities of automated feedback (AF) tools, especially those that are open by offering varying degrees of transparency and control to teachers. Using analytics and artificial intelligence, open AF tools permit automated processing and feedback with a speed, precision and scale that exceeds that of humans. This raises important questions about how human and machine feedback can be combined optimally and what is now required of teachers to use such tools skillfully. The paper addresses two research questions: Which teacher feedback competencies are necessary for the skilled use of open AF tools? and What does the skilled use of open AF tools add to our conceptions of teacher feedback competencies? We conduct an analysis of published evidence concerning teachers’ use of open AF tools through the lens of teacher feedback literacy, which produces summary matrices revealing relative strengths and weaknesses in the literature, and the relevance of the feedback literacy framework. We conclude firstly, that when used effectively, open AF tools exercise a range of teacher feedback competencies. The paper thus offers a detailed account of the nature of teachers’ feedback literacy practices within this context. Secondly, this analysis reveals gaps in the literature, signalling opportunities for future work. Thirdly, we propose several examples of automated feedback literacy, that is, distinctive teacher competencies linked to the skilled use of open AF tools.
So, all that’s to say that making arguments visible so that you and others can — in a very real sense — “see what you’re saying” has been a career-long passion. A key challenge in this long field of research has been that rigorous thinking is hard work. Bad luck, welcome to university! Argument Mapping and its related techniques use the affordances of visual trees/networks as an extended, external memory to augment personal and collective intelligence. Making one’s ideas visible as coherent diagrams is also hard work — but it’s good pain — the cognitive and discursive effort this entails is designed to clarify one’s thinking by revealing visually where the weaknesses are, in ways that writing and reading chunks of prose cannot tell you at a glance.
Enter NLP and rhetorical parsing
In 2012, we were now in the Web 2.0 era, and an exciting collaboration with NLP and linguistics expert Ágnes Sándor (Xerox) led to a new conception of Contested Collective Intelligence. For the first time in my work, machines could identify argumentative moves in sentences, complementing the argumentative moves that our web annotation tools enabled for people — who unlike machines, can of course can ‘read between the lines’ and see connections between ideas that may not even be in the texts.
This was extremely exciting, and the ideas and open source code carried through to our current Academic Writing Analytics project and web apps. I reflected on the impact of encountering NLP colleagues, in the context of The Future of Text book.
Conversational generative AI
And so we arrive at generative AI based on large language models, which advances the state of the art in language processing and generation in so many ways. Moreover, the conversational paradigm, when a chat application is overlaid, opens so many interesting human-computer/personal-collective intelligence possibilities. I’ve been intrigued to play with GPT-4 to see what its argument analysis capabilities are.
Previously, I’ve shared some early experiments on ChatGPT-3.5’s ability to identify implicit premises in prose arguments, and critique a flawed argument by analogy. I’ve now had the chance to experiment a little with the version of GPT-4 that is Bing Chat, accessed via Microsoft Edge browser. I was dying to see how far I could get in generating an Argument Map from a written argument.
The task is a typical analysis workflow, as prep for teaching:
search for relevant sources
select one for analysis
extract key elements of the argument and their relationships (described using a structured markdown notation called ArgDown)
diagram them to show their key relationships (in the ArgDown web app)
discuss (with the AI)
start thinking about student activities to help them learn
I don’t mind admitting that watching a machine do this for the first time was startling! I tell the story here…
Let’s take a closer look at what Bing Chat did, because it wasn’t perfect.
The gold stars signal what in my view are good summaries of what the authors said, correctly linked.
The blue info circles are “commentary” from Bing Chat about the arguments
The red crosses signal that the authors did not say this, it is a false reconstruction by Bing Chat.
The red underline signals classification of a premise using incorrect, or indeed made-up argument schemes. There is to my knowledge no such argument type as Argument from responsibility, or Argument from precaution. Argument from omission seems to be a jumbling of Fallacy of omission and Argument from ignorance.
If we take this node for example, it reads well as a summary:
However, the authors do not talk about researchers at all, they say:
As an amusing sidenote, Bing Chat was curiously resistant to recognising this, insisting that it was correct, first “quoting” a fabricated passage from the article to me, and then saying that this implied that the authors meant researchers. I thought that this sort of stubbornness had been ironed out after Bing Chat’s earlier escapades! More seriously, this points to the value of dialogic learning, with a partner who can be conversed with 24/7 — but who must still be treated with some caution, certainly at this stage of maturity.
To summarise:
Bing Chat showed intriguing capability, for a machine, to analyse an argumentative article:
extracting the key claim and underlying premises, summarising them in own words
(and without being asked to) attempting to classify some nodes using Walton’s Argumentation Schemes.
However it also introduced fallacious nodes (incorrect summaries of the authors, and incorrect commentary nodes), incorrect links, and argument classifications (inventing argument types, and/or misclassifying nodes).
This is an exploratory example, and more systematic evaluations are required, of the sort we see in the growing Argument Mining literature.
Reflections
It does feel to me that we’ve turned a corner in the long, wintry history of AI. Perhaps this is a passing summer, which will fade like the others. But in my own career, punctuated by eureka moments such as seeing my first Apple Mac, my first web page load, and an iPhone — this is up there.
University is to teach you to think. Argument analysis is serious intellectual work, of the sort that we would hope to see from our students. Nor is there always “one map to rule them all’ — a correct map, since like in spatial cartography, design decisions are made about scale and purpose. The point about knowledge cartography is that it provokes productive reflection and discourse. So even if the AI gets the map wrong (and it will), the conversation this should provoke should be useful. With colleagues Kirsty Kitty and Andrew Gibson, I’ve argued that embracing imperfection in tech can be productive if it promotes deeper critical thinking in learners, e.g., learning by correcting the automated output, or reflecting on questions it asks, or why it seems wrong. Students must, however, be scaffolded to engage in such activity.
Informal learning? This is feasible in formal education, but may be less attractive in other informal learning contexts where we want to promote critical deliberation, e.g. citizens engaged in a policy deliberation, many of whom lack the internal or external motivation to think that hard. But assuming future tools give more accurate argument maps/outlines, that require less debugging, perhaps we can see use-cases including:
assisting facilitators/educators to prepare learning resources for civic deliberations
assisting very engaged citizens to dissect complex arguments, and perhaps lowering the entry threshold for others who might otherwise not engage with such structured, critical deliberation
an article is very different to a multi-author conversation, but we can envisage summarising online discussions (NB: Teams is starting to summarise topics and actions in meeting transcripts)
Did we just supplant student cognition? From a learning sciences perspective, an overriding concern with generative AI is that it does too much cognitive work for the learner. Editing an AI-generated draft is not the same as wrestling with the blank page yourself. Ditto for reviewing an AI-generated argument map.
I have just done what many professionals have enjoyed doing in recent months: putting GPT through its paces to test its technical capability. But learners are not professionals: they don’t know what they don’t know. As I argue elsewhere, they may lack the knowledge, skills and dispositions to engage critically with AI output. They will require suitable scaffolding from mentors and teachers to learn what we mean by critical thinking and argument analysis, in order then to be equipped to use a power tool such as an argument mapping tool. Much empirical research awaits to test the affordances of generative AI like this, to establish when they are most useful to use developmentally, with a given age/stage of learner.
But we do know that argument mapping has struggled to gain traction (in formal education and among professionals) because it’s hard intellectual work. It could be that by generating full or intentionally incomplete argument maps, AI provides a step up for many learners to quickly get feedback on their work, or see examples of arguments about topics they are knowledgeable about — and thus better equipped to critique — compared to examples chosen by the teacher or textbook. Generative AI may open new possibilities because it can generate examples tuned to the interests of each learner, activating their curiosity to go deeper.
In this post, I share two ways to map your thinking, at different scales (rather like geographical maps)…
CQOCE Diagrams (or “Thesis Maps”)
One of the challenges that most/all PhD students have is to make their thinking visible — to themselves, to their supervisors, and to other researchers. There are so many potential ideas to weave into a narrative, and often different narrative pathways.
In our Learning Analytics PhD Program, we’ve been using the unpronounceable but very useful CQOCE diagram described by Luis Prieto in his Happy PhD blog. I encourage you to learn more about this:
“the diagram is commonly used in the introduction section of a dissertation, and it is meant to introduce, in graphical form, some of its main elements: the research Context, main research Question, Objectives, Contributions of your thesis and their Evaluation. However, many of us have also used it way before starting to write the dissertation book itself, as a “guiding star” when discussing with others and planning the thesis work.”
We have also been using it not just as a writing up device, but as a challenge right in the first year, to get doctoral researchers thinking about their thesis story. I tend to just call it the Thesis Map! As Luis comments, this goes through many revisions as the PhD takes its twists and turns. So in the end it serves two key purposes:
As a mirror for the supervision team to reflect on how we’re doing — “Oh, the contributions I thought I was making don’t align with the Research Questions…” “What kind of evaluation will be needed next year to back up this claimed Contribution 2?…”
As a navigational aid — a map — for the reader of the thesis, or indeed, for the audience if it’s used in a talk (“…in this talk I’ll be covering only this part of the map, but it shows you how this is a stage in a longer journey, in a wider landscape…”)
Here are two recent Learning Analytics theses that use this, from Vanessa Echeverria and Carlos Prieto.
Note that sections of the map can then be introduced in each chapter, to remind the reader where we are on the journey.
Argument Maps
The Thesis Map provides a macro-structure for the thesis argument: once you’ve bashed your map into shape, then your high level claim to have evidencedcontributions to advance knowledge that addresses important RQs just drops out naturally. But there will be many micro-level arguments in the thesis that are invisible at this scale.
Zooming in, we’re experimenting with Argument Maps, that make visible more detailed moves. Here’s my briefing during a PhD session which introduces some basics…
2 weeks later, a couple of researchers shared their maps for feedback, and both commented on how it helps clarify thinking. Thanks to Ben Hicks and Gloria Fernandez-Nieto for jumping in!
Ben used the freely accessible ArgDown website which uses a classic Argument Map notation, enriched with optional colour-coding from #tags:
Note:Al Selvin inventor and power user of Compendium, used it to create multimedia maps of his thesis thinking and qualitative data analysis [screen demos], incorporating many kinds of documents (which can be dragged and dropped onto maps).
One of the privileges of becoming a professor is to choose your title. Exciting but a challenge: encapsulate everything you’re passionate about in just a few words, which aren’t going to date too fast as thinking moves on.
I thought hard about this in 2014 when I was at The Open University UK. Learning Analytics was the hot new thing, but who knew how that was going to pan out? (very well as it happens!). But it seemed too early to nail all my colours to this mast.
There was a bigger picture, but what was its name? My home-base was Human-Computer Interaction, with the ACM CHI and BCS HCI conferences my stamping ground as a PhD student and early postdoc. But I’d moved into a range of other communities since, and at the OU the focus was now firmly on the role of knowledge media in shaping the future of learning. Human-Centred Computing was too broad, so how about Human-Centred Educational Technologies? Knowledge Media? Learning Technologies?
I reflected on which movements in HCI best expressed the richness of perspective that I found so exciting. And there it was staring me in the face: Informatics.
That definition comes from Kristen Nygaard‘s invited address to the 1986 World Computer Congress, entitled Program Development as a Social Activity. Informatics was a longstanding term in Europe, and was spreading in the US and elsewhere (perhaps in part as an extension of the move to creating broad, rich iSchools — someone more familiar than me with that history might comment on this).
So, I married Learning + Informatics. With the launch last year of the Learning Informatics Lab at University of Minnesota, I was delighted to be invited by Bodong Chen to give this talk (but sadly that trip was cancelled). However, we finally put that right this week, and here it is: why in my view Learning Informatics offers the depth and breadth we need to design learning analytics and AI in truly human-centred ways.
Dedicated to the extraordinary life and work of Kristen Nygaard! You will see in his reflections on the shaping of participatory design methods with trades unions and management, and definition of informatics, prescient ideas that are as vital now as then.
Learning Informatics: AI • Analytics • Accountability • Agency
Abstract: “Health Informatics”. “Urban Informatics”. “Social Informatics”. Informatics offers systemic ways of analyzing and designing the interaction of natural and artificial information processing systems. In the context of education, I will describe some Learning Informatics lenses and practices which we have developed for co-designing analytics and AI with educators and students. We have a particular focus on closing the feedback loop to equip learners with competencies to navigate a complex, uncertain future, such as critical thinking, professional reflection and teamwork. En route, we will touch on how we build educators’ trust in novel tools, our design philosophy of “embracing imperfection” in machine intelligence, and the ways that these infrastructures embody values. Speaking from the perspective of leading an institutional innovation centre in learning analytics, I hope that our experiences spark productive reflection around as the UMN Learning Informatics Lab builds its program.
The role of automated feedback systems in creating feedback-rich environments
Last week I hosted a 2 day dialogue, Designing Automated Feedback for Impact (DAFFI 2020). The original concept was to bring the editors and authors from The Impact of Feedback in Higher Education: Improving Assessment Outcomes for Learners (Eds. Henderson, Ajjawi, Boud & Molloy) to the UTS Connected Intelligence Centre, to spend 2 days in a workshop. The pandemic shifted this online, but the goals remain the same and moving online enabled us to more easily bring in additional participants.
“This book asks how we might conceptualise, design for and evaluate the impact of feedback in higher education. Ultimately, the purpose of feedback is to improve what students can do: therefore, effective feedback must have impact. Students need to be actively engaged in seeking, sense-making and acting upon any information provided to them in order to develop and improve. Feedback can thus be understood as not just the giving of information, but as a complex process integral to teaching and learning in which both teachers and students have an important role to play. The editors challenge us to ask two fundamental questions: when does feedback make a difference, and how can we recognise that impact?”
We call for a deeper dialogue between researchers in the design of assessment and feedback in higher education, and researchers developing automated-feedback tools using Learning Analytics/AI.
Perhaps we can learn from each other:
designers of automated feedback (for students or educators) are challenged on how they could build more robustly on principles of good feedback design;
researchers and educators working on feedback design are challenged as to whether automated feedback opens up new possibilities not taken into account in prior research;
potentially, new concepts may emerge that provide important language to clarify a changing design space for “feedback-rich environments” (as the book terms them);
new opportunities for learning analytics to tackle obstacles to the uptake of better feedback design practices;
identify topics for future events, and potential next steps.
Over two days, the book’s authors shared examples of this reconceptualisation of designing feedback for impact, and learning analytics researchers showed what is now possible with automated feedback. The extended dialogue was very rich, and we look forward to sharing the fruit from that as we reflect on how to take this forward.
10.30Identifying the Impact of Feedback Over Time and at Scale: Opportunities for Learning Analytics [slides]
Dragan Gaševic (Monash)
This talk explores how learning analytics can help educators design impactful feedback processes and support learners to identify the impact of feedback information, both across time and at scale. In doing so, it offers current examples of how learning analytics could guide policy and educational designs and be usefully employed to support learners to direct their own learning and study habits. This chapter also highlights how learning analytics can help individuals understand and optimise learning, and the environments in which the learning occurs.
30mins: Progress and challenges [Key ref: Book Chapter 12]
30mins: Questions and commentary / General discussion
11.40Break
11.55Automated Feedback on Collocated Teamwork & Classroom Proxemics [slides]
Our work with colleagues in Health focuses on how sensors and multimodal analytics enable automated feedback to nursing teams on embodied, collocated activity. Work with Science has used movement tracking to prototype automated feedback to educators on their use of teaching spaces.
30mins: Questions and commentary / General discussion
12.55Lunch
2.00Role of automated feedback in generating feedback-rich environment [slides]
Michael Henderson (Monash) and Rola Ajjawi (Deakin)
The challenges and opportunities of identifying, influencing and assessing feedback impact.
30mins: Overview – Feedback Research & Practice Challenges [Key ref: Book Chapters 2, 14 and 15] and Rola Ajjawi & David Boud (2018) Examining the nature and effects of feedback dialogue, Assessment & Evaluation in Higher Education, 43:7, 1106-1119, DOI: 10.1080/02602938.2018.1434128
30mins: Questions and commentary / General discussion
3.00Break
3.15Redesigning feedback involves addressing the feedback literacy of students and staff [slides]
David Boud (Deakin)
The challenge of building feedback literacy in students and staff
30mins: Overview Key refs Book Chapter 4 and:
Carless, D. and Boud, D. (2018). The development of student feedback literacy: enabling uptake of feedback, Assessment and Evaluation in Higher Education, 43, 8, 1315-1325. DOI: 10.1080/02602938.2018.1463354
Molloy, E., Boud, D. and Henderson, M. (2020) Developing a learner-centred framework for feedback literacy, Assessment and Evaluation in Higher Education, 45, 4, 527-540. DOI: 10.1080/02602938.2019.1667955
30mins: Questions and commentary / General discussion
4.15Reflections on Day 1
4.30Close
Wed 9 Sept (all times AEST)
10.15Fresh Croissants & Reflections for those who want to join early
10.30 Assessment and feedback design at scale [replay][slides]
Jaclyn Broadbent (Deakin)
This is a practice-based discussion of feedback design at scale in a context involving 1500 students. Discussion touches on improving understanding of standards, scaffolded assessment, high-quality audio feedback with feedforward aspects. This practice-based discussion will also mention the use of a tool known as Intelligent Agents which send automated feedback to students based on their digital activity as a way for staff and students to connect.
30mins: Questions and commentary / General discussion
11.30Break
11.45Examining impact and sense-making of personalised feedback messages using OnTask [replay][slides]
Lisa Lim & Abelardo Pardo (UniSA)
An OLT consortium has designed and is now piloting a platform called OnTask which enables an educator to design personalised feedback messages for hundreds of students at a time, based on their digital activity. Evidence is now emerging regarding the student and educator experience of such tools, and how their effectiveness can be judged.
30mins: Examining impact and sense-making of personalised feedback messages using OnTask
Lim, L.-A., Gentili, S., Pardo, A., Kovanović, V., Whitelock-Wainwright, A., Gašević, D., & Dawson, S. (2019). What changes, and for whom? A study of the impact of learning analytics-based process feedback in a large course. Learning and Instruction. doi:10.1016/j.learninstruc.2019.04.003
Lim, L.-A., Dawson, S., Gašević, D., Joksimović, S., Pardo, A., Fudge, A., & Gentili, S. (2020). Students’ perceptions of, and emotional responses to, personalised LA-based feedback: An exploratory study of four courses. Assessment & Evaluation in Higher Education. doi:10.1080/02602938.2020.1782831
30mins: Questions and commentary / General discussion
12.45Lunch
2.00Where have we got to?
Emerging themes, overlapping interests, next steps…
Significant work has focused on how we co-design automated feedback on writing with educators and students, leading to the refinement and release of an (open source) web tool called AcaWriter (orientation website for staff and students). This uses natural language processing to identify ‘rhetorical moves’ that are hallmarks of different genres of academic writing, in order to generate formative feedback.
Knight, S., Shibani, A., Abel, S., Gibson, A., Ryan, P., Sutton, N., Wight, R., Lucas, C., Sándor, Á., Kitto, K., Liu, M., Mogarkar, R. & Buckingham Shum, S. (2020). AcaWriter: A learning analytics tool for formative feedback on academic writing. Journal of Writing Research, 12, (1), 141-186. (Published online 12 April 2020). DOI: https://doi.org/10.17239/jowr-2020.12.01.06
Antonette Shibani, Simon Knight and Simon Buckingham Shum (2020). Educator perspectives on learning analytics in classroom practice. The Internet and Higher Education, Volume 46. Available online 20 February 2020. https://doi.org/10.1016/j.iheduc.2020.100730
Automated feedback on online engagement (any platform)
We co-designed and are now piloting a platform called OnTask which enables an educator to design personalised feedback messages or portals for hundreds of students at a time. Other institutions are embedding this or similar platforms (like ECoach and SRES), and evidence is now emerging regarding the student and educator experience of such tools, and how their effectiveness can be judged.
Introductions to OnTask and EClass: see these workshop videos
Lisa-Angelique Lim, Shane Dawson, Dragan Gašević, Srecko Joksimović, Abelardo Pardo, Anthea Fudge & Sheridan Gentili (2020) Students’ perceptions of, and emotional responses to, personalised learning analytics-based feedback: an exploratory study of four courses, Assessment & Evaluation in Higher Education, DOI: 10.1080/02602938.2020.1782831
Hamideh Iraj, Anthea Fudge, Margaret Faulkner, Abelardo Pardo, and Vitomir Kovanović. 2020. Understanding students’ engagement with personalised feedback messages. In Proceedings of the Tenth International Conference on Learning Analytics & Knowledge (LAK ’20). Association for Computing Machinery, New York, NY, USA, 438–447. DOI: https://doi.org/10.1145/3375462.3375527
Pardo, A., Bartimote, K., Buckingham Shum, S., Dawson, S., Gao, J., Gašević, D., Leichtweis, S., Liu, D., Martínez-Maldonado, R., Mirriahi, N., Moskal, A. C. M., Schulte, J., Siemens, G. and Vigentini, L. (2018). OnTask: Delivering Data-Informed, Personalized Learning Support Actions. Journal of Learning Analytics, 5(3), 235-249. doi:https://doi.org/10.18608/jla.2018.53.15
Roberto Martinez-Maldonado, Vanessa Echeverria, Gloria Fernandez Nieto, and Simon Buckingham Shum. 2020. From Data to Insights: A Layered Storytelling Approach for Multimodal Learning Analytics. In Proceedings of the 2020 CHI Conference on Human Factors in Computing Systems (CHI ’20). Association for Computing Machinery, New York, NY, USA, 1–15. DOI: https://doi.org/10.1145/3313831.3376148
Critical, human-centred, design of learning analytics
Broader perspectives that could help illuminate how we design Analytics/AI-augmented “feedback rich environments”.
Buckingham Shum, S.J. and Luckin, R. (2019), Learning analytics and AI: Politics, pedagogy and practices. British Journal of Educational Technology, 50, (6), pp.2785-2793. http://dx.doi.org/10.1111/bjet.12880
Buckingham Shum, S., Ferguson, R., & Martinez-Maldonado, R. (2019). Human-Centred Learning Analytics. Journal of Learning Analytics, 6(2), 1–9. https://doi.org/10.18608/jla.2019.62.1
Kitto, K., Buckingham Shum, S., & Gibson, A. (2018). Embracing imperfection in learning analytics. Proceedings of the 8th International Conference on Learning Analytics and Knowledge. Association for Computing Machinery, New York, NY, USA, pp.451–460. DOI: https://doi.org/10.1145/3170358.3170413
One of my PhDs is Sophie Abel, who’s published a free course on UTS Open — Writing an Abstract is about an hour’s tutorial introducing the hallmarks of a good abstract, providing a wide range of engaging interactive exercises.
The course is based on Sophie’s PhD, who brings her expertise in Academic Language & Learning to the challenge of designing automated feedback to Higher Degree by Research (HDR) students (completing Masters and Doctoral dissertations) on their writing (learn more).
The course concepts of understanding and mastering the key rhetorical moves in an Abstract are carried through intoAcaWriter‘s Abstract genre, the tool we’ve released to all UTS students, that gives instant formative feedback on drafts. But you have access to this via Writing an Abstract!
The term “Classroom Proxemics” refers to how teachers and students use classroom space, and the impact of this and the spatial design on learning and teaching. While learning analytics is usually thought of in terms of capturing, analysing and feeding back activity that is mediated by a collaborative platform, one can now be teaching and learning face-to-face, whilst also generating digital traces from embodied activity (as well as being online via one or more platforms).
Roberto Martinez-Maldonado (who pioneered our work on multimodal learning analytics to support nursing teams in simulated wards) has developed a new strand of work, on the potential of tracking (with consent of course), how educators make use of learning spaces as they teach. Working closely with academics in the Science and Health Faculties, the results of which are now being published, and demonstrate:
the process we use to work closely with educators to co-design potentially invasive technologies in ethical ways
the potential educators see in being able to visualise their teaching practice in this way
the problems they perceive with such tools if they are used in appropriately
The term “Classroom Proxemics” refers to how teachers and students use classroom space, and the impact of this and the spatial design on learning and teaching. This paper addresses the divide between, on the one hand, substantial work on proxemics based on classroom observations and, on the other hand, emerging work to design automated feedback that helps teachers identify salient patterns in their use of the classroom space. This paper documents how digital analytics were designed in service of a senior teacher’s practice-based inquiry into classroom proxemics. Indoor positioning data from four teachers were analysed, visualised and used as evidence to compare three distinct learning designs enacted in a physics classroom. This paper demonstrates how teachers can make effective use of such visualisations, to gain insight into their classroom practice. This is evidenced by i) documenting teachers’ reflections on visualisations of positioning data, both their own and that of peers; and ii) identifying the types of indicator (operationalised as analytical metrics) that foreground the most useful information for teachers to gain insight into their practice.
Automatic tracking of activity and location in the classroom is becoming increasingly feasible and inexpensive. However, although there is a growing interest in creating classrooms embedded with tracking capabilities using computer vision and wearables, more work is still needed to understand teachers’ perceived opportunities and concerns about using indoor positioning data to reflect on their practice. This paper presents results from a qualitative study, conducted across three authentic educational settings, investigating the potential of making positioning traces available to teachers. Positioning data from 28 classes taught by 10 university teachers was captured using sensors in three different collaborative classroom spaces in the disciplines of design, health and science. The contributions of this paper to ubiquitous computing are the documented reflections of teachers from different disciplines provoked by visual representations of their classroom positioning data and that of others. These reflections point to: i) the potential benefit of using these digital traces to support teaching; and ii) concerns to be considered in the design of meaningful analytics systems for instructional proxemics.
Learning Analytics (LA) systems can offer new insights into learners’ behaviours through analysis of multiple data streams. There remains however a dearth of research about how LA interfaces can enable effective communication of educationally meaningful insights to teachers and learners. This highlights the need for a participatory, horizontal co-design process for LA systems. Inspired by the notion of translucence, this paper presents LAT-EP (Learning Analytics Translucence Elicitation Process), a five-step process to design for the effective use of translucent LA systems. LAT-EP was operationalised in an authentic multimodal learning analytics (MMLA) study in the context of teamwork in clinical simulation. Results of this process are illustrated through a series of visual proxies co-designed with teachers, each presenting traces of social, physical, affective and epistemic evidence captured while teams of student nurses practised clinical skills in a simulated hospital setting.
Buckingham Shum, S.J. & Luckin, R. (2019). Learning Analytics and AI: Politics, Pedagogy and Practices. British Journal of Educational Technology, 50(6), pp.2785-2793. https://doi.org/10.1111/bjet.12880 | PDF | HTML
I’m delighted to say that this BJET 50th Anniversary Special Issue is now online. The 11 contributions, from leading research teams in Learning Analytics, and Artificial Intelligence in Education (LA/AIED), provide critical, reflective accounts from researchers who are also system developers. Together, they bring a deep understanding of the design decisions, and value commitments, that underpin the emerging digital infrastructure for education.
This extract from our editorial sets out the critiques and challenges for LA/AIED to which this volume responds:
“The fears are reasonable: that quantification and autonomous systems provide a new wave of power tools to track and quantify human activity in ever higher resolution—a dream for bureaucrats, marketeers and researchers—but offer little to advance everyday teaching and learning in productive directions. This fear is justified in our post‐Snowden era of pervasive surveillance, and post‐Cambridge Analytica data breaches. Partly however, this fear is also born of lack of awareness about the diverse forms that LA/AIED take, which is equally understandable—to outsiders, these are new and opaque technologies. It follows that if we do not want to see concerned students, parents and unions protesting against AI in education, we need urgently to communicate in accessible terms what the benefits of these new tools are, and equally, how seriously the community is engaging with their potential to be used to the detriment of society.
Politics, pedagogy and practices
This special issue provides resources to tackle this challenge, by engaging with these concerns under the banner of three themes: Politics, Pedagogy and Practices:
1. The politics theme acknowledges the widespread anxiety about the ways that data, algorithms and machine intelligence are being, or could be, used in education. From international educational datasets gathered by governments and corporations, to personal apps, in a broad sense ‘politics’ infuse all information infrastructures, because they embody values and redistribute power. While applauding the contributions that science and technology studies, critical data studies and related fields are making to contemporary debates around the ethics of big data and AI, we wanted to ask, how do the researchers and developers of LA/AI tools frame their work in relation to these concerns?
2. The pedagogies theme addresses the critique from some quarters that LA/AI’s requirements to formally model skills and quantify learning processes serve to perpetuate instructivist pedagogies (eg, Wilson & Scott, 2017), branded somewhat provocatively as behaviourism (Watters, 2015). While there has clearly been huge progress in STEM‐based intelligent tutoring systems (see du Boulay, 2019; Rosé, McLaughlin, Liu, & Koedinger, 2019), what is the counter‐argument that LA/AI empowers more diverse pedagogies?
3. The practices theme sought accounts of how these technologies come into being. What design practices does one find inside LA/AI teams that engage with the above concerns? Moreover, once these tools have been deployed, what practices do educators use to orchestrate these tools in their teaching?”
[…]
“In the context of this 50th Anniversary Special Issue of the British Journal of Educational Technology, authors from a range of disciplinary backgrounds and outlooks were challenged to make the state of the art in their fields accessible to a broad audience, and to give glimpses of the road ahead to 2025. The papers are therefore primarily reflective, “big picture” narratives, reviewing and discussing existing literature and case studies, and looking forward to what could, or should, be on the horizon. Together, they provide an eclectic set of lenses for thinking about LA/AIED at a range of scales—from the macroscale of national and international policy and stakeholder networks, to the meso‐scale of institutional strategy, down to the micro‐scale of how we make cognitive models more intelligible, or design decisions more ethical.”
The abstracts and links for the 11 articles are appended below for convenience, and the entire issue is freely accessible until the end of the year, so grab your copies!
Digital data are transforming higher education (HE) to be more student‐focused and metrics‐centred. In the UK, capturing detailed data about students has become a government priority, with an emphasis on using student data to measure, compare and assess university performance. The purpose of this paper is to examine the governmental and commercial drivers of current large‐scale technological efforts to collect and analyse student data in UK HE. The result is an expanding data infrastructure which includes large‐scale and longitudinal datasets, learning analytics services, student apps, data dashboards and digital learning platforms powered by artificial intelligence (AI). Education data scientists have built positive pedagogic cases for student data analysis, learning analytics and AI. The politicization and commercialization of the wider HE data infrastructure is translating them into performance metrics in an increasingly market‐driven sector, raising the need for policy frameworks for ethical, pedagogically valuable uses of student data in HE.
Data—their collection, analysis and use—have always been part of education, used to inform policy, strategy, operations, resource allocation, and, in the past, teaching and learning. Recently, with the emergence of learning analytics, the collection, measurement, analysis and use of student data have become an increasingly important research focus and practice. With (higher) education having access to more student data, greater variety and nuanced/granularity of data, as well as collecting and using real‐time data, it is crucial to consider the data imaginary in higher education, and, specifically, analytics as performative politics. Data and data analyses are often presented as representing “reality” and, as such, are seminal in institutional “truth‐making,” whether in the context of operational or student learning data. In the broader context of critical data studies (CDS), this social cartography examines and maps the “data frontier” and the “data gaze” within the context of the dominant narrative of evidence‐based management and the data imaginary in higher education. Following an analysis of the main assumptions in evidence‐based management and the power of metrics, this paper presents a social cartography of data analytics not only as representational, but as actant, and as performative politics.
Rosemary Luckin & Mutlu Cukurova, University College London
Interdisciplinary research from the learning sciences has helped us understand a great deal about the way that humans learn, and as a result we now have an improved understanding about how best to teach and train people. This same body of research must now be used to better inform the development of Artificial Intelligence (AI) technologies for use in education and training. In this paper, we use three case studies to illustrate how learning sciences research can inform the judicious analysis, of rich, varied and multimodal data, so that it can be used to help us scaffold students and support teachers. Based on this increased understanding of how best to inform the analysis of data through the application of learning sciences research, we are better placed to design AI algorithms that can analyse rich educational data at speed. Such AI algorithms and technology can then help us to leverage faster, more nuanced and individualised scaffolding for learners. However, most commercial AI developers know little about learning sciences research, indeed they often know little about learning or teaching. We therefore argue that in order to ensure that AI technologies for use in education and training embody such judicious analysis and learn in a learning sciences informed manner, we must develop inter‐stakeholder partnerships between AI developers, educators and researchers. Here, we exemplify our approach to such partnerships through the EDUCATE Educational Technology (EdTech) programme.
Yi-Shan Tsai, University of Edinburgh
Oleksandra Poquet, National University of Singapore
Dragan Gašević, Monash University
Shane Dawson & Abelardo Pardo, University of South Australia
Learning analytics (LA) has demonstrated great potential in improving teaching quality, learning experience and administrative efficiency. However, the adoption of LA in higher education is often beset by challenges in areas such as resources, stakeholder buy‐in, ethics and privacy. Addressing these challenges in a complex system requires agile leadership that is responsive to pressures in the environment and capable of managing conflicts. This paper examines LA adoption processes among 21 UK higher education institutions using complexity leadership theory as a framework. The data were collected from 23 interviews with institutional leaders and subsequently analysed using a thematic coding scheme. The results showed a number of prominent challenges associated with LA deployment, which lie in the inherent tensions between innovation and operation. These challenges require a new form of leadership to create and nurture an adaptive space in which innovations are supported and ultimately transformed into the mainstream operation of an institution. This paper argues that a complexity leadership model enables higher education to shift towards more fluid and dynamic approaches for LA adoption, thus ensuring its scalability and sustainability.
Kirsty Kitto & Simon Knight, University of Technology Sydney
Artificial intelligence and data analysis (AIDA) are increasingly entering the field of education. Within this context, the subfield of learning analytics (LA) has, since its inception, had a strong emphasis upon ethics, with numerous checklists and frameworks proposed to ensure that student privacy is respected and potential harms avoided. Here, we draw attention to some of the assumptions that underlie previous work in ethics for LA, which we frame as three tensions. These assumptions have the potential of leading to both the overcautious underuse of AIDA as administrators seek to avoid risk, or the unbridled misuse of AIDA as practitioners fail to adhere to frameworks that provide them with little guidance upon the problems that they face in building LA for institutional adoption. We use three edge cases to draw attention to these tensions, highlighting places where existing ethical frameworks fail to inform those building LA solutions. We propose a pilot open database that lists edge cases faced by LA system builders as a method for guiding ethicists working in the field towards places where support is needed to inform their practice. This would provide a middle space where technical builders of systems could more deeply interface with those concerned with policy, law and ethics and so work towards building LA that encourages human flourishing across a lifetime of learning.
As technology has become ubiquitous in learning contexts, there has been an explosion in the amount of learning data. This creates opportunities to draw on the decades of learner modelling research from Artificial Intelligence in Education and more recent research on Personal Informatics. We use these bodies of research to introduce a conceptual model for a Personal User Model for Life‐long, Life‐wide Learners (PUMLs). We use this to define a core set of system competency questions. A successful PUML and its interface must enable a learner to answer these by scrutinising their PUML, aided by its scaffolding interfaces. We aim to give learners both control over their own learning data and the means to harness that data for the important metacognitive processes of self‐monitoring, reflection and planning. We conclude with a set of design guidelines for creating PUMLs. Our core contribution is a way to think about the design and evaluation of learning data and applications so that they give learner control and agency beyond simple data access and algorithmic transparency.
Deborah Richards, Macquarie University
Virginia Dignum, Umea Universitet Teknisk-Naturvetenskaplig Fakultet; Technische Universiteit Delft
Pedagogical Agents (PAs) that would guide interactions in intelligent learning environments were envisioned two decades ago. These early animated characters had been shown to deliver learning benefits. However, little was understood regarding what aspects were beneficial for learning and what sort of learning PAs were suitable for. This article considers the current and future use of PAs to support and challenge learners from three perspectives. Firstly, we look at PAs from a practical perspective to consider what Intelligent Virtual Agents are, the roles they play in education and beyond and the underlying technologies and theories driving them. Next we take a pedagogical perspective to consider the vision, pedagogical approaches supported and new possible uses of PAs. This leads us to the political perspective to consider the values, ethics and societal impacts of PAs. Drawing all three perspectives together we present a design for values approach to designing ethical and socially responsible PAs.
Intelligent Tutoring systems (ITSs) and Intelligent Learning Environments (ILEs) have been developed and evaluated over the last 40 years. Recent meta‐analyses show that they perform well enough to act as effective classroom assistants under the guidance of a human teacher. Despite this success, they have been criticised as embodying a retrograde behaviourist technology. They have also been caught up in broader controversies about the role of Artificial Intelligence in society and about the entry of big data companies into the education market and the harvesting of learner data. This paper concentrates on rebutting the criticisms of the pedagogy of ITSs and ILEs. It offers examples of how a much wider range of pedagogies are available than their critics claim. These wider pedagogies operate at both the screen level of individual systems, as well as at the classroom level within which the systems are orchestrated by the teacher. It argues that there are many ways that such systems can be integrated by the teacher into the overall experience of a class. Taken together, the screen‐level and orchestration‐level dramatically enlarge the range of pedagogies beyond what was possible with the “Skinner Box.”
Manolis Mavrikis & Eirini Geraniou, University College London
Sergio Gutierrez Santos & Alexandra Poulovassilis, Birkbeck, University of London
While it is commonly accepted that Learning Analytics (LA) tools can support teachers’ awareness and classroom orchestration, not all forms of pedagogy are congruent to the types of data generated by digital technologies or the algorithms used to analyse them. One such pedagogy that has been so far underserved by LA is exploratory learning, exemplified by tools such as simulators, virtual labs, microworlds and some interactive educational games. This paper argues that the combination of intelligent analysis of interaction data from such an Exploratory Learning Environment (ELE) and the targeted design of visualisations has the benefit of supporting classroom orchestration and consequently enabling the adoption of this pedagogy to the classroom. We present a case study of LA in the context of an ELE supporting the learning of algebra. We focus on the formative qualitative evaluation of a suite of Teacher Assistance tools. We draw conclusions relating to the value of the tools to teachers and reflect with transferable lessons for future related work.
Carolyn P. Rosé & Elizabeth A. McLaughlin, Carnegie Mellon University
Ran Liu, MARi, LLC
Kenneth R. Koedinger, Carnegie Mellon University
Using data to understand learning and improve education has great promise. However, the promise will not be achieved simply by AI and Machine Learning researchers developing innovative models that more accurately predict labeled data. As AI advances, modeling techniques and the models they produce are getting increasingly complex, often involving tens of thousands of parameters or more. Though strides towards interpretation of complex models are being made in core machine learning communities, it remains true in these cases of “black box” modeling that research teams may have little possibility to peer inside to try understand how, why, or even whether such models will work when applied beyond the data on which they were built. Rather than relying on AI expertise alone, we suggest that learning engineering teams bring interdisciplinary expertise to bear to develop explanatory learner models that provide interpretable and actionable insights in addition to accurate prediction. We describe examples that illustrate use of different kinds of data (eg, click stream and discourse data) in different course content (eg, math and writing) and toward different goals (eg, improving student models and generating actionable feedback). We recommend learning engineering teams, shared infrastructure and funder incentives toward better explanatory learner model development that advances learning science, produces better pedagogical practices and demonstrably improves student learning.
Petr Johanes & Candace Thille, Stanford University
Education and education research are experiencing increased digitization and datafication, partly thanks to the rise in popularity of massively open online courses (MOOCs). The infrastructures that collect, store and analyse the resulting big data have received critical scrutiny from sociological, epistemological, ethical and analytical perspectives. These critiques tend to highlight concerns and/or warnings about the lack of the infrastructures’ and builders’ understanding of various nontechnical aspects of big data research (eg seeing data as neutral rather than as products of social processes). These critiques have primarily come from outside of the builder community, rendering the conversation largely one‐sided and devoid of the voices of the builders themselves. The purpose of this paper is to re‐balance the conversation by reporting the results of interviews with 11 data infrastructure builders in higher education institutions. The interviews reveal that builders engage deeply with the issues the critiques outline, not only thinking about them, but also developing practices to address them. The paper focuses the findings on three themes: designing a productive science, navigating ubiquitous ethics and achieving real human impact. Researchers, policymakers and infrastructure builders can use these accounts to better understand the building process and experience.
Following the tragically premature death of Al Selvin in October 2015, I continued to think about how his inspirational research can live on in more than research writings. Friends and colleagues were discussing ways in which we could communicate the ideas behind Knowledge Art to reflective practitioners, in contrast to the more academic audiences we’d been engaging with.
One outcome of this came to fruition as learning resources for the University of Technology Sydney’s Master of Data Science & Innovation, specifically, for the subject I coordinated at the time, Data Visualisation & Narrative.
I prepared a reading based on the book (Publisher/Facebook) tuned to our data science students, with an assessment based on a role-play scenario that gave students the chance to practise their ‘knowledge artistry’. (This is linked to real data challenges that our students engage in with TransportNSW and the NSW Data Analytics Centre, here in Sydney.)
These are Creative Commons-licensed open access resources — do let me know if you find them useful for your own thinking, especially teaching/coaching.


 “This book asks how we might conceptualise, design for and evaluate the impact of feedback in higher education. Ultimately, the purpose of feedback is to improve what students can do: therefore, effective feedback must have impact. Students need to be actively engaged in seeking, sense-making and acting upon any information provided to them in order to develop and improve. Feedback can thus be understood as not just the giving of information, but as a complex process integral to teaching and learning in which both teachers and students have an important role to play. The editors challenge us to ask two fundamental questions: when does feedback make a difference, and how can we recognise that impact?”


